10 Things to Know About Survey Experiments
Survey experiments are experiments conducted within a survey. They are widely used to study the prevalence of sensitive attitudes and behaviors and of complex preferences. This guide describes several common types of survey experiments – conjoint experiments, priming experiments, endorsement experiments, list experiments (item count technique), and randomized response experiments – and some key considerations for their design and analysis.
1 What is a survey experiment?
A survey experiment is an experiment conducted within a survey. Survey respondents are randomly assigned to two or more experimental conditions (also known as treatment arms), and because of this randomization, differences in survey responses across groups can be interpreted as effects of the difference in treatment conditions, plus some random noise.
2 Why do a survey experiment?
Survey experiments are useful when a regular survey, without experimentation, may generate biased or even nonsensical responses about individual survey respondents’ attitudes, preferences, or behaviors. For example, if researchers are interested in studying the effects of some information on support for a policy, directly asking each survey respondent “how does this information affect your support for the policy?” may raise concerns about the accuracy and truthfulness of the responses. Regular surveys may similarly not be able to reliably measure complex, multidimensional preferences through individual self-reports. Direct questioning techniques may also understate the prevalence of attitudes and behaviors, such as racist attitudes and illegal activities, with which respondents do not want to be publicly associated. In these situations, survey experiments help to measure the prevalence of attitudes, preferences, and behaviors for a respondent pool better than regular surveys. As with other randomized experiments, survey experiments are generally used to estimate features of the group rather than specific individuals.
3 Conjoint experiments
Conjoint experiments are useful for measuring preferences that are characterized by more than one attribute (multidimensional preferences). In a typical conjoint experiment, researchers repeatedly ask respondents to choose between two distinct options and randomly vary the characteristics of these two options.1 Researchers may also ask respondents to rate each option on a scale. In both cases, respondents express their preferences toward a large number of options with randomized attributes.
Hainmueller et al. (2014) demonstrate the use of conjoint experiments in a study about support for immigration. The authors showed respondents two immigrant profiles and asked (a) which immigrant the respondent would prefer be admitted to the Unites States and (b) how the respondent rated each immigrant on a scale from 1-7. The authors randomly varied nine attributes of the immigrants (gender, education, employment plans, job experience, profession, language skills, country of origin, reasons for applying, and prior trips to the United States), yielding thousands of unique immigrant profiles. This process was repeated five times so that each respondents saw and rated five pairs of immigrants. Through this procedure, the authors assessed how these randomly varied components influence support for the immigrant.
Respondents saw:
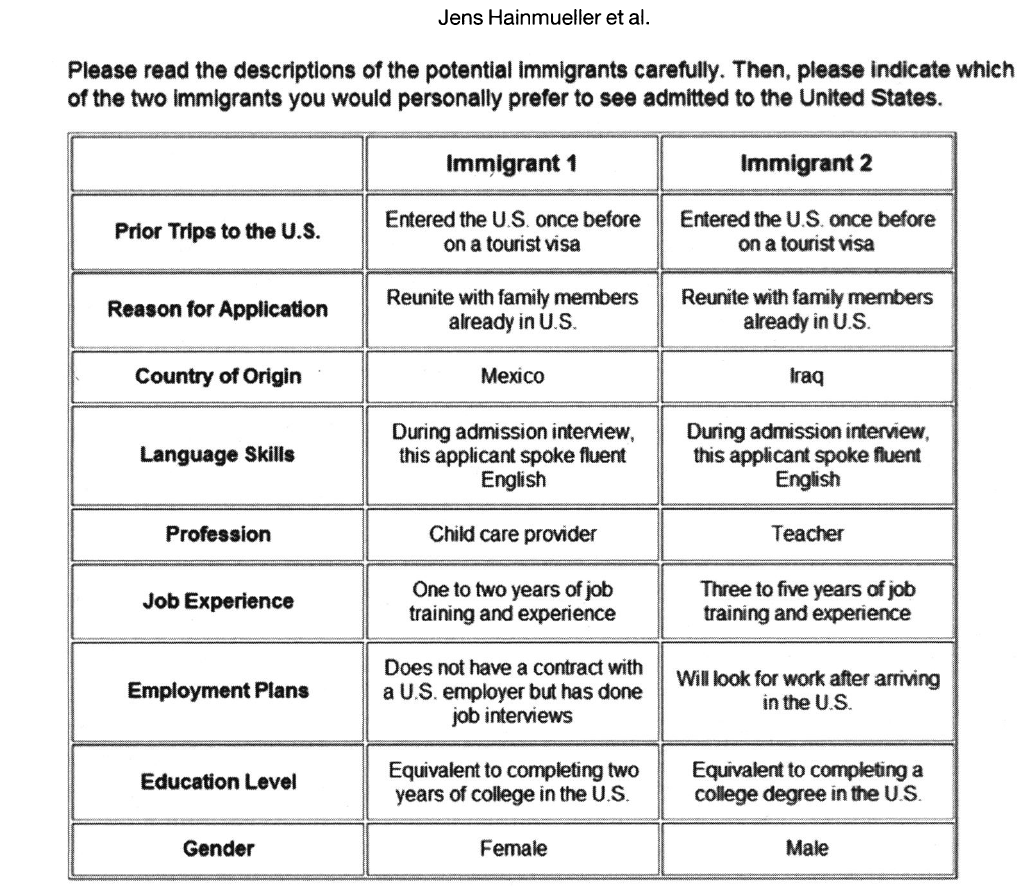
The conjoint experiment thus allows us to measure how multiple immigrant characteristics, such as their gender or country of origin, shape respondents’ attitudes toward the immigrants. Another advantage of this survey experiment, compared to a non-experimental survey, is that it preempts the need for respondents to directly express sensitive preferences; instead, they indirectly reveal their preferences. For example, while respondents who hold sexist attitudes may be less willing to openly express preferences for male immigrants due to social desirability bias, they may find it more comfortable to choose — and therefore reveal their preferences for — male immigrant profiles in this less direct setting.2
4 Priming experiments
Priming experiments are a broad class and include any experiment that makes a specific topic salient in the mind of the respondent. Respondents in the treatment group are exposed to a stimulus representing topic X in order to influence their considerations at the top of their head when responding to a survey question about topic Y. The control group, however, is not exposed to the stimulus. The difference in expressed preferences regarding Y between the treatment and control groups is attributed to exposure to the treatment stimulus.
Images are commonly used for priming. For example, Brader et al. (2008) used images to measure the role of race in shaping immigration preferences. The researchers showed subjects a positive or negative news article about immigration paired with a picture of a European immigrant or an Hispanic immigrant. Subjects expressed negative attitudes about immigration when the negative news article was paired with the Hispanic immigrant picture but not in other conditions. The picture primed people to think about Hispanic immigrants, and thinking about Hispanic immigrants reduced support for immigration compared to thinking about European immigrants.
More broadly, priming experiments can be useful when researchers are interested in learning about the influence of context. By making a specific context of interest salient to a randomized subset of respondents, researchers can gauge the impact of this primed context on the measured outcome of interest.
5 Endorsement experiments
Endorsement experiments measure attitudes toward a potentially sensitive object, usually a controversial political actor or group. In a typical endorsement experiment, respondents are asked how much they support a policy. In the treatment condition, the policy is said to be endorsed by an actor or a group. In the control condition, however, this endorsement information is omitted. The average difference in support between the endorsed and unendorsed policy represents the change in support for the policy because of the endorsement of the actor or group.
For example, Nicholson (2012) used an endorsement experiment to study partisan bias in the United States during the 2008 Presidential campaign. The researchers asked respondents about policies, varying whether the policy was endorsed by the Presidential candidates of the two main political parties, Barack Obama (Democrat) and John McCain (Republican). Respondents were told:
As you know, there has been a lot of talk about immigration reform policy in the news. One proposal [backed by Barack Obama/backed by John McCain] provided legal status and a path to legal citizenship for the approximately 12 million illegal immigrants currently residing in the United States. What is your view of this immigration reform policy?
On one hand, the difference between the control condition and the Obama (McCain) condition for Democrats (Republicans) indicates in-party bias. On the other, the difference between the control condition and the Obama (McCain) condition for Republicans (Democrats) indicates out-party bias. This experiment helps researchers gauge the favorability toward the potentially sensitive item (i.e., the political actor).
Because endorsement experiments preempt the need for respondents to self-report their support for a controversial object, they are especially useful in politically sensitive contexts. For example, they have been used to measure public support for militant groups (e.g., Bullock et al. (2011); Lyall et al. (2013)).
6 List Experiments
List experiments (also known as the item count technique) measure the prevalence of a sensitive attitude or behavior in the respondent pool when researchers expect respondents may not respond truthfully to a direct question. For example, respondents may be reluctant to admit that they hold racially conservative views (Kuklinski et al. 1997) or engage in illegal behaviors (García-Sánchez and Queirolo 2021) even after being assured of anonymity.
In a standard list experiment, the researcher randomly assigns respondents to a control or treatment condition. The control condition presents respondents with a list of items; the treatment condition presents respondents with the same list plus a treatment item indicating the attitude or behavior of interest. Respondents are then asked how many of these items apply to them. The average difference between the treatment and control conditions estimates the percentage of respondents for whom the treatment item applies.
For example, Kuklinski et al. (1997) studied racial animus with a list experiment. They told respondents:
Now I am going to read you three things that sometimes make people angry or upset. After I read all three, just tell me HOW MANY of them upset you. I don’t want to know which ones, just HOW MANY.
(1) the federal government increasing the tax on gasoline
(2) professional athletes getting million-dollar contracts
(3) large corporations polluting the environment
(4) a black family moving in next door
In the above example, the fourth item was withheld from the control condition. The authors found that the mean number of items chosen in the treatment group was 2.37, compared to 1.95 in the control group. The difference of 0.42 between treatment and control suggests that 42% of respondents would be upset by a black family moving in next door.
Despite the cover for the sensitive attitude or behavior provided by a list experiment, respondents may still worry that their response reflects their attitudes about the sensitive item since a respondent’s attitude toward each item can be determined if the respondent answers that all or none of the items apply to them. Respondents then may increase or decrease their response to portray themselves in a better light (Leary and Kowalski 1990). New types of list experiments, including double list experiments (Glynn 2013) and placebo-controlled list experiments (Riambau and Ostwald 2019), have been developed to address these concerns.
7 Randomized Response
The randomized response technique is also used to measure the prevalence of a sensitive attitude or behavior when the researcher expects that respondents may not respond truthfully to a direct question.3 In the most common version of the randomized response technique, respondents are directly asked a yes or no question about a sensitive topic. The respondent is also given some randomization device, such as a coin or die. The respondent is told to answer the question when the randomization device takes on a certain value (e.g., tails) or to simply say “yes” when the randomization device takes a different value (e.g., heads). The idea is that because a “yes” response could reflect the outcome of the randomization device or agreement with the sensitive item, respondents will feel able to respond truthfully.
For example, Blair et al. (2015) studied support for militants in Nigeria with the randomized response technique. They gave respondents a die and had the respondent practice throwing it. They then told respondents:
For this question, I want you to answer yes or no. But I want you to consider the number of your dice throw. If 1 shows on the dice, tell me no. If 6 shows, tell me yes. But if another number, like 2 or 3 or 4 or 5 shows, tell me your opinion about the question that I will ask you after you throw the dice.
[ENUMERATOR TURN AWAY FROM THE RESPONDENT]
Now throw the dice so that I cannot see what comes out. Please do not forget the number that comes out.
[ENUMERATOR WAIT TO TURN AROUND UNTIL RESPONDENT SAYS YES TO]: Have you thrown the dice? Have you picked it up?
Now, during the height of the conflict in 2007 and 2008, did you know any militants, like a family member, a friend, or someone you talked to on a regular basis? Please, before you answer, take note of the number you rolled on the dice.
In expectation, one-sixth of respondents answer “yes” due to the die throw. The researcher can thus determine what percentage of respondents engaged in the sensitive behavior. Here, however, respondents might not feel that their answers to randomized response questions were truly anonymous.4 Other types of randomized response techniques, including the repeated randomized response technique and the crosswise model, address this limitation. Azfar and Murrell (2009) and Jann et al. (2011) explain the logic and implementation of these techniques.
8 Implementation
To implement survey experiments, researchers need to write up multiple versions of a survey: at least one for the control condition(s) and at least one for the treatment condition(s). Then, researchers need a randomization device that allows them to randomize the survey version shown to the respondents. There are many platforms that facilitate the implementation of survey experiments, with Qualtrics being one of the most popular tools among survey researchers.
While the treatment is typically imposed through text, the treatment stimulus can also be images or videos or in other formats. The key is to map the treatment directly onto the theoretical variable of interest. That is, if the researcher is interested in studying the effect of X on Y, the text, image, or video (or any of their combination) should induce a change in X and not in other confounding variables.5 Visual aids, if carefully provided, can be helpful in different settings. For example, researchers have used photos as experimental stimuli to investigate the impact of candidate appearance on vote choice (Ahler et al. 2017) and the effects of gender and racial diversity in shaping the legitimacy of international organizations (Chow and Han 2023).
9 Considerations
Survey experiments can be an effective tool for researchers to measure sensitive attitudes and learn about causal relationships. Not only can they be done quickly and iteratively, but they may also be included on mass online surveys because they do not require in-person contact to implement. This means that a researcher can plan a sequence of online survey experiments, changing the intervention and measured outcomes from one experiment to the next to learn about the mechanisms behind the treatment effect very quickly (Sniderman 2018).
One key consideration is the strength of the treatment. Sometimes the experimental stimulus is unable to generate a meaningful change in the subsequently measured attitude or behavior not because the treatment is unrelated to the outcome variable of interest, but because the treatment itself is too weak. For example, for an information provision experiment where the experimental stimulus is some factual information related to topic Y, the treatment may fail to change views on Y not because the information plays no role in shaping individual attitudes toward Y, but because respondents have already been exposed to this information in the real world.6 More generally, researchers need to watch out for pretreatment effects (Druckman and Leeper 2012). If respondents, before participating in the survey experiment, have already encountered the experimental stimulus, there may be no measured difference between treatment and control groups because all respondents were “pretreated” with the stimulus, including those in the control group.
But researchers need to be careful about survey satisficing, which occurs when respondents put in minimal effort to understand and answer a survey question.7 In the presence of satisficing behavior, the treatment embedded in the survey experiments may not be received by respondents as intended. As such, the measured preferences will be unreliable. Given this concern, researchers should always design survey experiments that are easy to understand. The length and complexity of the survey and experimental stimuli should also be kept at a minimum level, whenever possible. A related consideration is respondent attentiveness, an issue that is extensively discussed by Alvarez et al. (2019).
Question wording and ordering also matter, as they do for regular surveys. Some terms, for example, may be unfamiliar to certain respondents or interpreted by different respondents in different ways. Where a question appears on a survey may affect how individuals provide their responses (Gaines et al. 2007).
10 Limitations
While survey experiments offer a fruitful way to measure individual preferences, researchers are often more concerned about real-world outcomes. When preferences are measured — and treatments are delivered — in a survey setting, there is no guarantee that the survey-experimental findings will translate into the real world. Boas et al. (2019), for example, find very different effects of information about corruption on support for incumbents in survey experiments and field experiments conducted in the same setting. Therefore, researchers should be cautious when they extrapolate from survey experiments (Barabas and Jerit 2010). For more discussions on the strengths and limitations of survey experiments, see:
- Mutz (2011) “Population-Based Survey Experiments.”
- Sniderman (2018) “Some Advances in the Design of Survey Experiments” in the Annual Review of Political Science.
- Lavrakas et al. (2019) “Experimental Methods in Survey Research: Techniques that Combine Random Sampling with Random Assignment.”
- Diaz et al. (2020) “Survey Experiments and the Quest for Valid Interpretation” in the Sage Handbook of Research Methods in Political Science and International Relations.